Running enterprise IT on-premises costs more than most finance teams realize — and the gap widens every year. Hardware refresh cycles, underutilized servers, and the engineering hours spent keeping legacy systems alive all compound into a structural cost problem that capital investment alone can’t fix.
Cloud migration changes the equation. It shifts infrastructure from a fixed, depreciating asset into a variable, consumption-based resource — and it does so while reducing the operational burden on IT teams. The result is a lower total cost of ownership, faster delivery cycles, and the ability to scale without proportional spending.
This article breaks down where on-premise infrastructure bleeds money, how a well-executed migration addresses each source of waste, and what long-term financial performance looks like once cloud-native operations are established.
- On-premise infrastructure drains budget in three ways: over-provisioned hardware that sits idle, maintenance costs that run regardless of usage, and engineering hours lost to legacy upkeep.
- Elastic cloud resources scale with demand, without a proportional increase in infrastructure spend.
- Cloud-native architectures reduce operational overhead through automation, managed services, and infrastructure-as-code.
- Accurate ROI measurement tracks both direct savings and indirect gains.
The Cost Challenges of Traditional On-Premise IT Infrastructure
Before examining what the cloud saves, it’s worth understanding where on-premise infrastructure costs actually originate — because the problem runs deeper than hardware invoices. There are three distinct cost sources, and each one compounds the others:
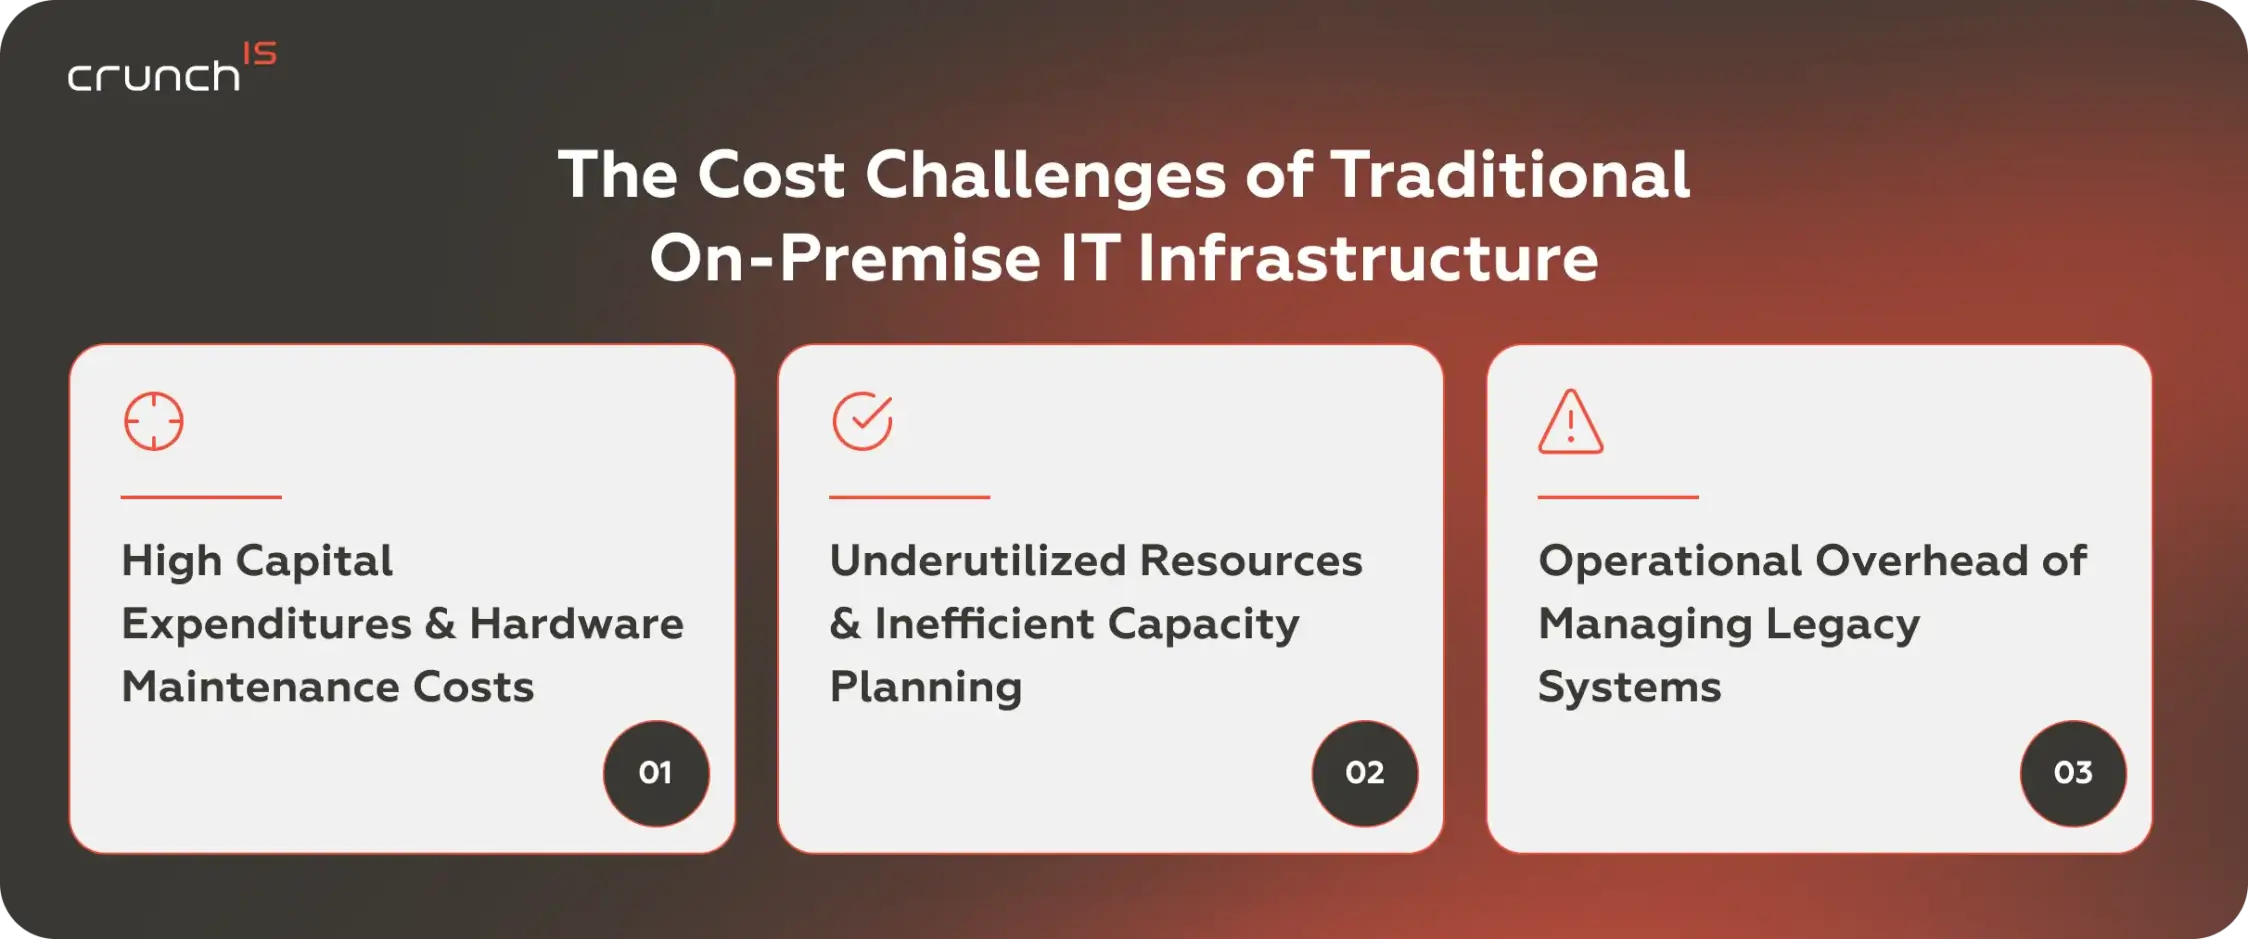
1. High Capital Expenditures and Hardware Maintenance Costs
The first cost is visible and unavoidable: on-premise infrastructure requires significant upfront capital. Servers, storage arrays, networking equipment, and data center facilities must all be purchased, installed, and depreciated over multi-year cycles. Hardware refresh cycles typically run three to five years — but business requirements shift faster than procurement schedules.
The result: companies either over-provision (buying capacity they won’t use for years) or under-provision (creating performance bottlenecks at the worst possible time).
Beyond acquisition, maintenance compounds the problem. Warranty contracts, licensed support agreements, physical replacement of failed components, and the facilities costs to power and cool the hardware all run continuously. These costs exist regardless of how much of the infrastructure is actually in use.
2. Underutilized Resources and Inefficient Capacity Planning
The second cost is less visible but equally damaging: most of that hardware sits idle most of the time. On-premise environments are provisioned for peak load (a quarterly processing spike, a product launch, a period of high concurrent users) and then carry that full capacity as overhead for the rest of the year.
It’s an inherent limitation of fixed infrastructure. When demand drops, the costs don’t. When demand spikes beyond projections, the infrastructure can’t respond fast enough to avoid degraded performance.
For IT teams, this creates a perpetual balancing act between cost efficiency and risk mitigation. Idle infrastructure still needs to be patched, monitored, and maintained — and that work falls on engineers who could be building something instead. Which brings us to the third cost.
3. Operational Overhead of Managing Legacy Systems
Legacy system maintenance absorbs a disproportionate share of IT resources. Patch management, version upgrades, integration troubleshooting, manual provisioning, and incident response all require skilled engineering time.
The older the system, the worse the overhead:
- documentation erodes,
- engineers who built the original architecture leave, and
- dependencies accumulate.
What started as a maintainable system becomes a fragile, hard-to-modify constraint on the entire organization’s technical velocity.
Taken together, these three cost sources are precisely what a well-structured cloud migration is designed to eliminate.
How Cloud Migration Reduces IT Costs and Improves Efficiency
A well-planned migration doesn’t address these three cost sources one at a time. It restructures how IT costs are generated, tracked, and controlled across all three simultaneously.
Shifting from CapEx to OpEx with Pay-As-You-Go Models
The most immediate financial change after cloud migration is the shift from capital expenditure (CapEx) to operating expenditure (OpEx). Instead of purchasing and depreciating hardware, organizations pay for the compute, storage, and networking they actually consume — typically on hourly or per-second billing cycles.
For finance teams, this is significant. CapEx requires upfront capital commitments and multi-year depreciation schedules that can misalign with the actual delivery of business value. OpEx aligns cost directly with usage, making IT spend easier to forecast, attribute, and control.
For engineering teams, it means infrastructure decisions are reversible. Environments can be spun up for a project and terminated when no longer needed. Resources can be rightsized based on observed usage patterns rather than projected peak demand.
In a recent Crunch-IS engagement, a US-based healthcare organization eliminated $150K–$300K in on-premise hardware refresh costs within 10 weeks of migrating a revenue-critical scheduling and billing system to AWS — without touching the application code or disrupting clinical operations.

Reducing Infrastructure and Maintenance Expenses
Once workloads move to a managed cloud environment, large categories of on-premise costs disappear or shrink substantially:
- hardware acquisition and refresh cycles are replaced by provider-managed infrastructure, updated continuously without customer-side capital investment;
- data center facilities transfer to the provider;
- vendor maintenance contracts for hardware are eliminated, replaced by platform-level SLAs;
- manual provisioning labor gives way to infrastructure-as-code and automated deployment pipelines.
Organizations moving to managed cloud services also reduce engineering overhead across OS patching, database administration, and backup management. The provider owns that layer of operations. The internal team focuses on application logic and business capability.
That reallocation is where cloud migration benefits become tangible beyond the invoice: less budget consumed by keeping the lights on means more available for what moves the business forward. Once infrastructure and maintenance costs are contained, the next lever is operational efficiency — and that’s where automation does the bulk of the work.
Automation and Managed Services Driving Operational Efficiency
Cloud platforms come with a native automation layer built in. Auto-scaling adjusts capacity to match demand in real time. Managed databases handle replication, failover, and patching automatically. CI/CD pipelines replace manual deployment steps with repeatable, auditable processes.
The operational impact is measurable:
- incident response times drop when infrastructure can be replaced rather than repaired;
- deployment frequency increases when release pipelines eliminate manual gates;
- engineering capacity redirects from maintenance to delivery when platforms handle routine operations automatically.
Cloud migration software and DevOps tooling accelerate this transition by enabling teams to treat infrastructure as code — versioned, tested, and deployed through the same processes as application software. The result is an IT operation that runs leaner, responds faster, and requires fewer people to keep it stable.
Long-Term Cost Savings and Business Value of Cloud Migration
Migration reduces costs immediately through the elimination of hardware, lower maintenance, and less manual labor. What compounds over time is different:
- the ability to scale without buying new infrastructure,
- ship faster without provisioning delays, and
- redirect engineering capacity toward work that actually drives business growth.
Scalability and Cost Control Through Elastic Resources
Elastic infrastructure changes the economics of growth. Organizations no longer need to provision for projected future scale — they provision for current demand and scale dynamically as that demand materializes.
This matters most at the extremes. A sudden traffic spike that would have taken down an on-premise environment routes seamlessly to additional compute in a cloud environment, then releases that capacity when the spike passes. A new business unit or product line can be stood up in days, not the weeks required to procure and provision physical hardware.
For organizations pursuing cloud transformation solutions as part of a broader growth strategy, this elasticity is a competitive capability. The ability to test, scale, and wind down initiatives without proportional infrastructure commitment lowers the risk profile of strategic experimentation.
Optimizing IT Operations with Cloud-Native Architectures
Application migration to the cloud unlocks architectural patterns that simply aren’t viable on-premise. Microservices with independent scaling, serverless compute for event-driven workloads, managed data pipelines, multi-region deployments for availability and latency optimization — each becomes a practical option once the infrastructure constraint is gone.
Each pattern reduces a specific category of operational cost:
- microservices allow individual components to be scaled or updated without touching the rest of the system;
- serverless eliminates the cost of idle compute — the function runs when invoked and costs nothing when idle;
- managed data services eliminate DBA overhead for routine operations.
Cloud-to-cloud migration follows the same logic. Some organizations have already moved to the cloud but ended up with the wrong architecture — over-provisioned instances, underused reserved capacity, or general-purpose environments running specialized workloads. The fix is the same cost discipline: right-size resources, cut what isn’t used, and replace self-managed services with managed equivalents that the provider runs better.
Measuring ROI and Total Cost of Ownership (TCO) After Migration
ROI from cloud migration is real, but it requires measurement to capture — and the indirect savings are often larger than the direct ones. They’re just harder to put on a spreadsheet. Engineering time redirected from maintenance to delivery, faster time-to-market, reduced incident response costs, and lower risk exposure from automated patching all compound over time in ways that a one-time TCO calculation won’t fully capture.
The direct savings are more straightforward:
- eliminated hardware refresh spend,
- reduced facilities costs,
- vendor maintenance contracts that no longer apply, and
- staffing hours no longer consumed by infrastructure upkeep.
Cloud providers publish TCO calculators as a starting point, but accurate analysis requires detailed input about current on-premise spend, utilization patterns, and planned workload growth.
Cloud migration consulting services supply that analysis and translate it into an architecture that delivers the projected savings (rather than creating new ones).
Why Crunch-IS Is a Leading Company for Cloud Migration Services
Crunch-IS is a full-service technology partner with 8+ years of experience and 150+ engineers and consultants delivering Cloud and DevOps, custom software development, AI/ML, and data engineering solutions for clients across the US, UK, Canada, and the DACH region.
Our cloud practice is built on engineering depth, not vendor certification counts.
Proven Expertise in Cloud Strategy and Migration Planning
Migration without a strategy is expensive. We’ve seen organizations lift-and-shift workloads to the cloud, discover their costs increased, and then spend months undoing architectural decisions that made sense on-premise but not in a cloud billing model.
Crunch-IS engagements start with a technical and cost assessment:
- current infrastructure inventory,
- utilization analysis,
- dependency mapping, and
- a migration roadmap that sequences workloads by complexity and business impact.
The strategy determines which workloads should be rehosted, re-platformed, refactored, or retired — and in what order.
When we migrated a patient scheduling and billing system to AWS for a US healthcare organization, the engagement ran 10 weeks from assessment to stabilization — on time, within scope, and with 99.9%+ availability from day one. Disaster recovery time dropped from up to 8 hours to under 15 minutes. And infrastructure-related support tickets fell by 50%.
Our cloud migration consulting services cover strategy through execution, with engineering accountability at every stage.
Cost-Optimized Cloud Architectures and FinOps Approach
Rightsizing is not a one-time activity. Cloud spend grows organically — new environments get provisioned, old ones don’t get terminated, reserved capacity gets underused, and costs accumulate in ways that aren’t visible without active governance.
Crunch-IS designs cloud architectures with cost observability built in from day one: tagging strategies that attribute spend to teams and workloads, alerting on cost anomalies, and regular rightsizing reviews based on actual consumption data. We apply FinOps principles throughout the engagement as an ongoing operational discipline.
Secure, Scalable, and Business-Focused Migration Solutions
Security is a common concern in discussions about cloud migration services, and it’s a legitimate one. Moving workloads to shared infrastructure requires deliberate security architecture — network segmentation, identity and access management, encryption in transit and at rest, and compliance controls appropriate for the client’s regulatory environment.
Crunch-IS integrates security from the architecture phase. We implement DevSecOps practices, automated security scanning in CI/CD pipelines, and compliance-ready configurations for regulated industries. Our Site Reliability Engineering (SRE) practice ensures that availability and performance targets are defined, measured, and maintained post-migration.
Every engagement is scoped around business outcomes:
- reduced costs,
- improved reliability,
- faster delivery,
- or all three.
We don’t propose migrations for their own sake. We scope them around the specific value they’ll deliver, with measurement criteria established before the work begins.