AI-Powered Water Main Failure Prediction Platform (MLOps & Predictive Asset Management)

42%
fewer unexpected failures
28%
lower emergency maintenance costs (projected)
AI-Powered Water Main Failure Prediction Platform (MLOps & Predictive Asset Management) | Crunch-IS Case Study
We built a predictive asset intelligence platform on Google Cloud that scores every pipe segment by failure probability and consequence — giving engineering teams a prioritized, risk-based intervention list instead of reactive break response.
Industry:

Water & Wastewater Utilities

Location:

UK

Team Size:

6

Duration:

6 months

Technologies
GCP
Cloud Storage
Dataproc
BigQuery
Vertex AI
Dataflow
XGBoost
01

About the Client

The client is a large UK-based water and wastewater utility responsible for thousands of kilometers of underground distribution and collection infrastructure. It serves millions of residential and commercial customers across urban and rural areas and manages a diverse portfolio of aging assets, including water mains, wastewater pipelines, pumping stations, and associated network infrastructure.

As part of its digital transformation and AMP investment planning programs, the organization set out to use AI and predictive analytics to improve asset management decisions, reduce service disruptions, and allocate capital more effectively.
AI-Powered Water Main Failure Prediction Platform (MLOps & Predictive Asset Management) | Crunch-IS Case Study
02

Challenge

Water main failures were one of the utility’s most expensive operational problems. Replacement decisions relied on asset age, periodic inspections, and engineering judgment — a process that made it difficult to identify which underground pipes were most likely to fail next.

When a pipe burst unexpectedly, the consequences compounded: service outages, emergency repair costs, water losses, regulatory exposure, and customer impact. The organization held large volumes of historical maintenance records, GIS data, environmental information, and operational telemetry — but had no scalable way to turn that data into ranked, actionable risk predictions.

The dataset added its own complexity. Across hundreds of thousands of pipe segments, actual failures represented less than 1% of assets in any given year. Predicting rare failure events accurately, while keeping false positives manageable, required specialized feature engineering, sampling strategies, and model evaluation techniques.

The client needed a solution that would:

  • Identify high-risk assets before failure.
  • Give engineering teams a prioritized intervention list.
  • Support explainability requirements.
  • Integrate with existing enterprise systems.
  • Establish a repeatable MLOps framework for future AI work.
03

Solution We Delivered

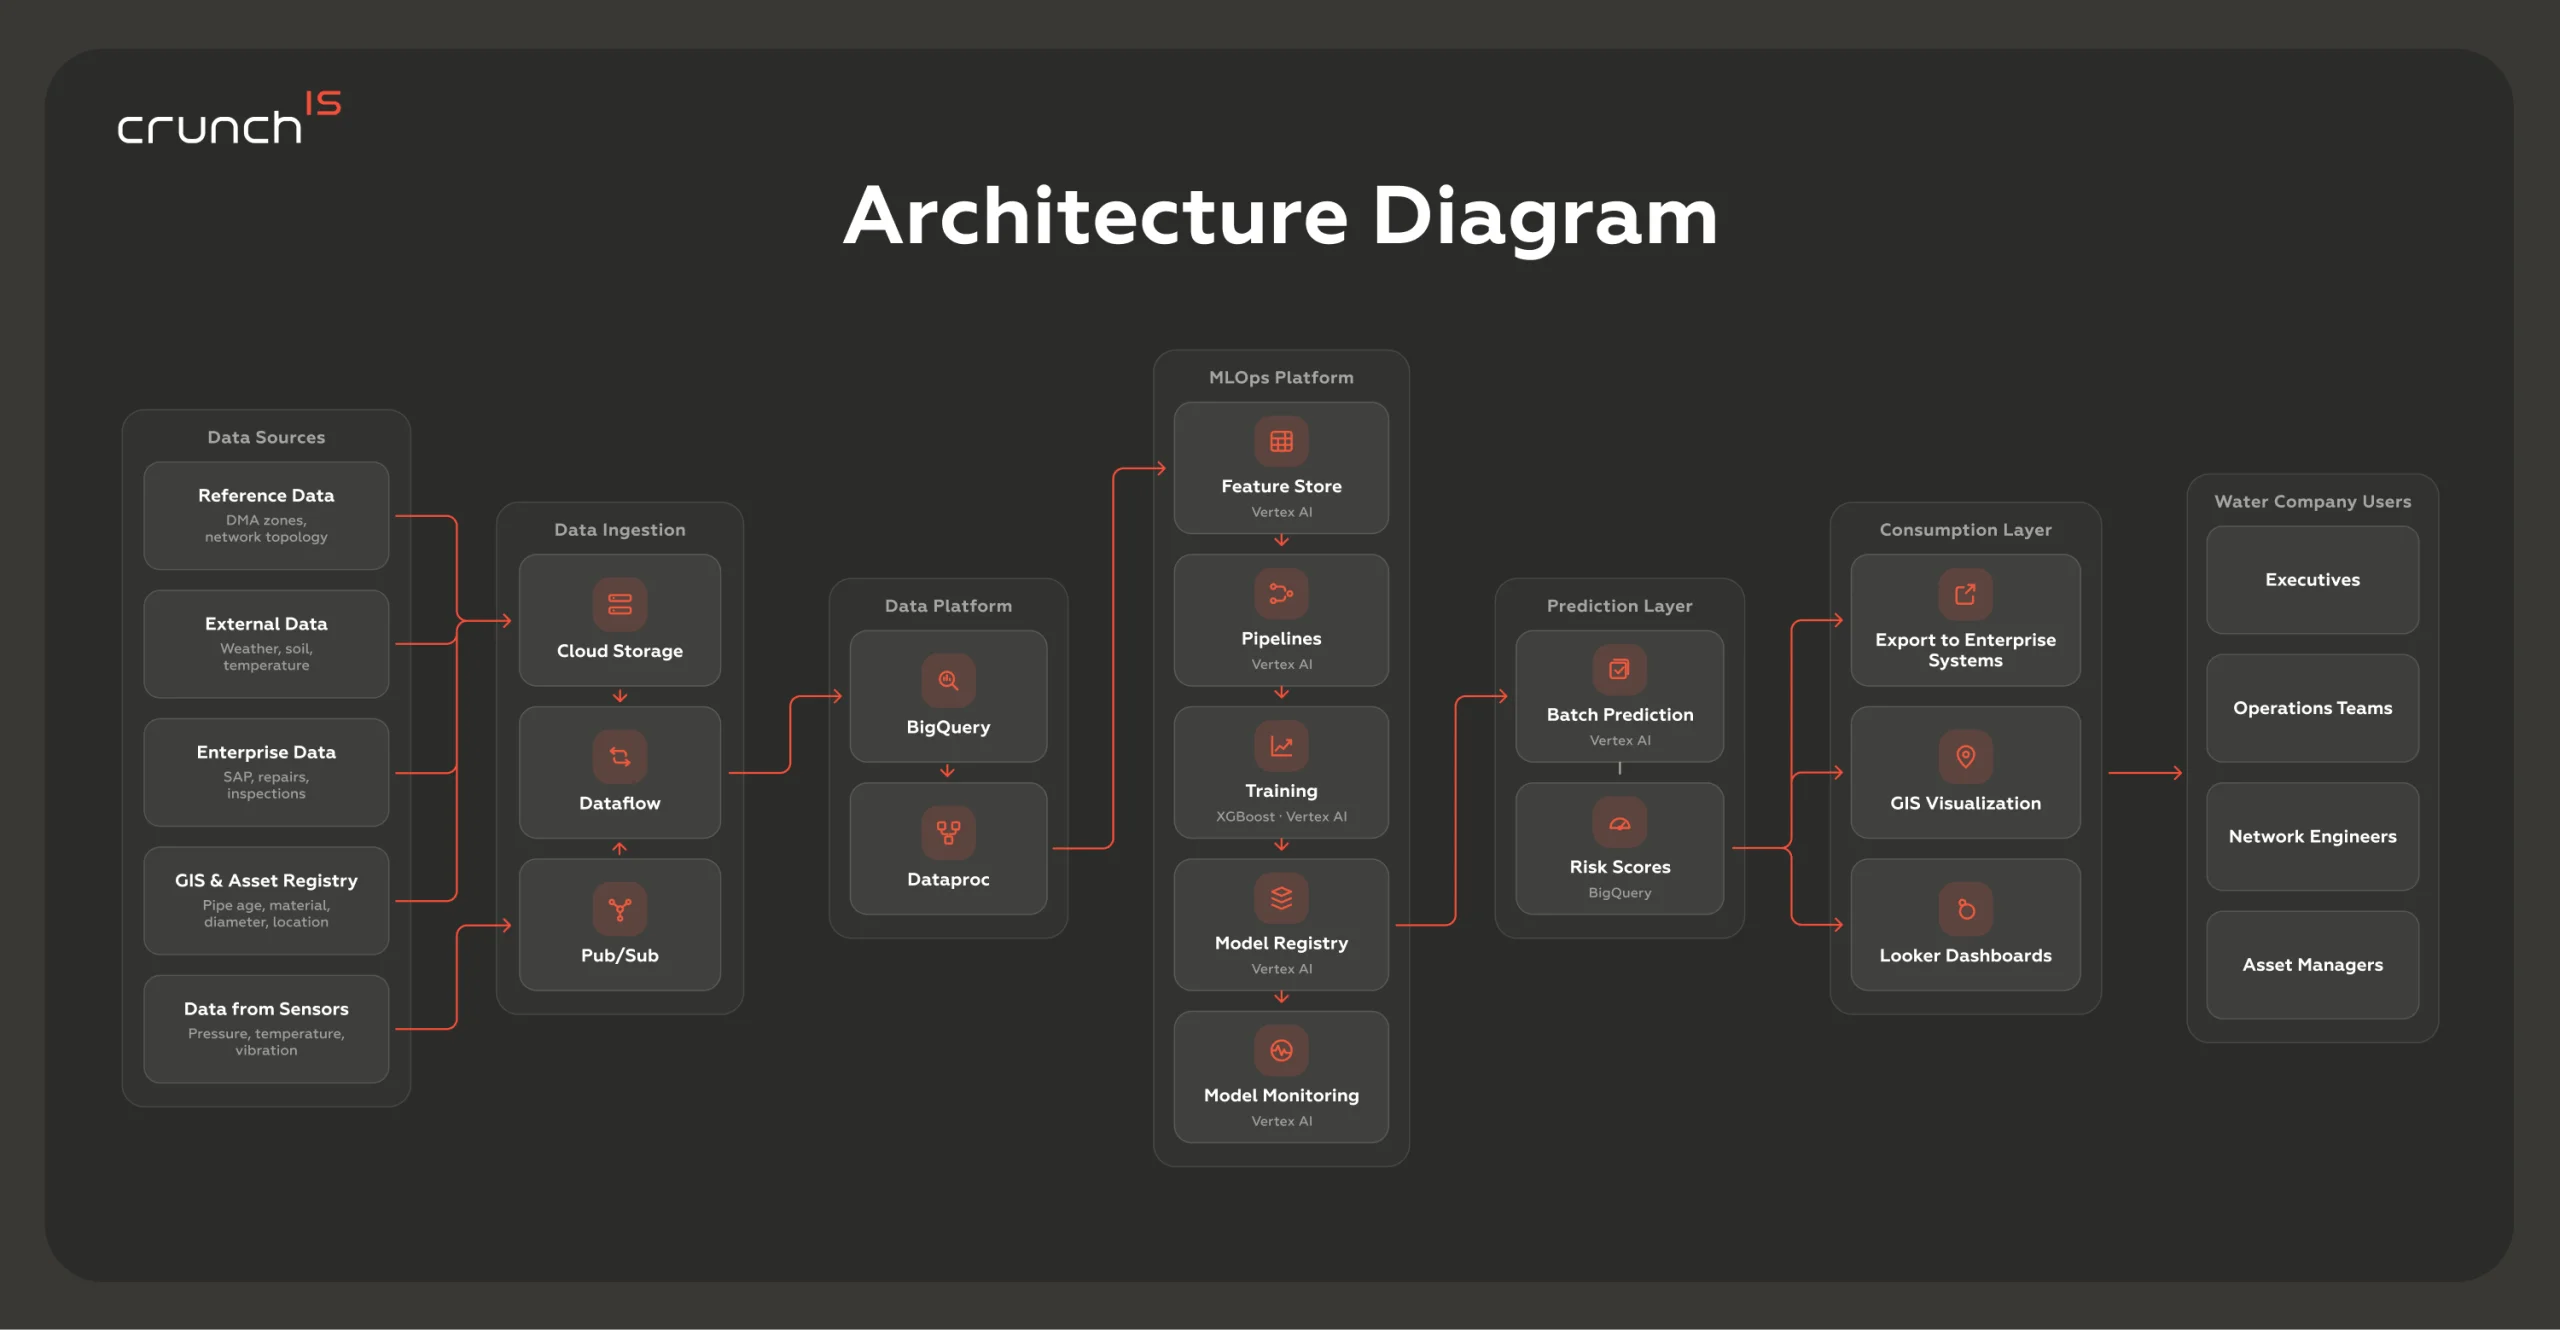
We delivered a predictive asset intelligence platform on Google Cloud that included:

Risk-Based Prioritization

Using Vertex AI and XGBoost, the platform generates a failure-probability score for each pipe segment. That score is combined with asset criticality factors — affected customers, proximity to critical infrastructure, environmental impact, and estimated repair cost — to produce a composite risk score:

Risk Score = Probability of Failure × Consequence of Failure

This gives engineering teams a ranked list of intervention candidates to review, rather than treating every high-probability prediction as an automatic repair trigger.

End-to-End MLOps Pipeline

We implemented a complete MLOps pipeline using Vertex AI Pipelines, Feature Store, Model Registry, Cloud Composer, and Cloud Build. The pipeline automates data processing, feature engineering, model training, validation, deployment, monitoring, and periodic retraining. A feedback loop captures new failures, maintenance actions, and updated operational data to improve the model over time.

Production-Grade Infrastructure

The platform includes CI/CD, production model monitoring, feature drift detection, model versioning, and a GIS-enabled dashboard for asset managers and engineers. Every component was built to support ongoing operations.

Crunch-IS image case study
04

Client’s Results

The platform shifted the utility from break-driven maintenance to risk-based intervention. Engineering teams now work from a prioritized asset list rather than responding to failures after the fact — supporting better AMP investment planning and more predictable capital allocation.

The platform also delivered:

42% Reduction in Unexpected Failures (Back-Tested)

During 12-month historical back-testing and simulation against 5 years of asset and failure data, assets predicted as high-risk and flagged for proactive intervention showed a 42% reduction in unexpected failures compared to the baseline.

28% Projected Reduction in Emergency Maintenance Costs

Proactive intervention on high-risk assets is projected to reduce emergency repair costs by 28% — shifting spend from unplanned emergency response to planned, lower-cost maintenance.

A Reusable MLOps Foundation

The automated pipeline, model governance framework, and monitoring infrastructure give the utility a repeatable foundation for future AI and ML initiatives across the asset portfolio.

Have a Question? Let’s Get in Touch!

Tell us what you’re building or where you’re stuck. We work with engineering and product teams on custom software, AI & ML, cloud infrastructure, DevOps, and UI/UX — from early scoping to long-term delivery. One conversation is usually enough to know whether we’re the right fit.

Email: [email protected]

    I have read and accepted the Terms of Use and Privacy Policy *

    We and our partners use technology such as cookies on our site to personalize content and ads, provide social media features, and analyze our traffic. Click “Accept” to consent to the use of this technology across the web.

    Decline