
Don't see yours? Start with a conversation.
Talk to an AI expertCrunch-IS in numbers
- 170+
- experts
- 120+
- delivered projects
- 40+
- active customers
- 6+
- locations
- 8+
- years of experience

Home / Data Engineering Services
Data Engineering Services
We design and build data pipelines, platforms, and integrations that perform in real production conditions — applying an AI-enabled development approach, cloud-native tooling, and structured engineering practices to make your data infrastructure reliable, observable, and ready to support decisions at scale.
Benefits of Data Engineering Services

Validation checks, monitoring rules, and automated alerts keep data clean and consistent across every pipeline. Your team stops reconciling reports manually and starts acting on results that are already verified.

When pipelines run reliably, and data is structured for access, analysts and product teams stop waiting on engineering. The time between a business question and a trustworthy answer compresses significantly.

Pipelines designed with proper error handling, retry logic, and observability require far less hands-on maintenance. Engineering effort shifts from firefighting broken jobs to building new capabilities.

Every transformation is documented, and every source is mapped. When a compliance requirement or data quality issue surfaces, your team can trace it directly — without having to reverse-engineer the pipeline from scratch.
Ready to build data pipelines you can rely on?
Data Engineering Services We Offer

Data Pipeline Development
We design and build ETL and ELT pipelines that move data reliably from source to destination — covering structured ingestion, automated transformations, error handling, and recovery logic. Every pipeline is tested against realistic failure scenarios before it reaches production, and monitoring is built in from the start.

Data Migration Services
We handle migrations from legacy systems, on-premises databases, and cloud-to-cloud environments. The engagement covers source mapping, schema reconciliation, data cleansing, staged transfer execution, and post-migration validation against agreed acceptance criteria. Nothing is signed off on a single cutover event.

Data Engineering Consulting
We assess your current data architecture, identify where reliability, performance, lineage, security, or maintainability gaps are costing your team — in time, risk exposure, or engineering overhead — and deliver a prioritized technical roadmap. Consulting engagements deliver clear direction and can transition directly into implementation if the scope warrants it.

Data Platform Engineering
We design and configure the storage, compute, and access layers that your pipelines run on top of — including warehouse and lakehouse setup on AWS, Azure, GCP, or on-premises environments, schema design, storage optimization, and access control. The goal is a platform your team can operate and extend without constant vendor involvement.
Our Capabilities
ETL/ELT Architecture and Orchestration
We design and implement ETL and ELT workflows, selecting the right pattern based on transformation complexity, latency requirements, and platform characteristics.
Real-Time and Batch Processing
We build systems that handle streaming data alongside batch processing workflows for scheduled, high-volume loads.
AI-Enabled Pipeline Automation
We integrate AI-driven components into data pipeline workflows — automated anomaly detection, intelligent schema drift alerts, self-healing retry logic, and LLM-assisted data transformation for unstructured or semi-structured sources.
Data Quality and Observability
We implement schema validation, row-level quality checks, consistency rules, and anomaly detection using frameworks. Alerts trigger on deviations before they propagate downstream.
Secure Data Architecture
Access controls, encryption at rest and in transit, audit logging, and role-based permissions are incorporated into the platform architecture during the design phase.
What You Get

Scope Defined Before Build
Data environment assessment, pipeline requirements, and acceptance criteria are agreed upon before development starts. You know what is being built, how it will be measured, and what it looks like when it’s done.

AI-Accelerated Data Engineering Delivery
We embed AI tooling across the data engineering lifecycle — from pipeline scaffolding and transformation logic to automated quality checks and post-launch monitoring. Build cycles compress without adding headcount.
Documentation Your Team Can Operate From
Pipeline architecture, transformation logic, data dictionaries, and platform configuration are documented and handed over as working reference material. Your team can maintain, extend, and troubleshoot the system on their own.

Post-Launch Monitoring Period
Every engagement includes a defined post-launch monitoring period. If something drifts after go-live, we are still accountable — adjustments happen before they become incidents.
What Our Clients Say About Us
They come up with lots of scalable and best-practice ideas that enable us to achieve what we have right now.
Crunch-IS was great at leading us on what good should look like and bringing our ideas to life for evaluation and review.

Crunch-IS impressed me with is the quality of developers. It is simply much better than in any other company we’ve tried working with.

We are impressed with their performance, how they are engaged with product development, and how they care about the product.

It’s been a very enjoyable experience. All has been fantastic about communicating, and working.

Our partnership with Crunch-IS has been an invaluable resource as we’ve scaled.

What I found in Crunch-IS was the technical competency, ability to think outside the box, and very good English.

They have a large impact on the whole architecture we ended up with. Overall, I’ve been pleased and impressed with everything Crunch-IS did for us.

Crunch-IS impressed us with their technical excellence and the sheer ‘meeting of minds and cultures’ and open, honest exchanges. This was not a decision we took lightly, and 5 months into the engagement we continue to be really impressed with how Crunch-IS approach the collaboration, and we’re delighted with the calibre of the team we have working with us.

Working with Crunch-IS was easy. They were patient with us as we worked through the contract questions and patient again as we were getting our billing set up. The design work was elegant and the developer delivered the app we had contracted for on time and good quality.

The team at Crunch-IS was very nice to work with. They worked diligently and were very professional. When questions or technical problems arose, they answered them quickly and were always ready and kind about helping us.

Crunch-IS developer helped us deliver an important feature for our project much faster than expected.

Crunch-IS facilitated a seamless, collaborative effort throughout the project. The team maintained open lines of communication, kept detailed records of task assignments, and adhered to project timelines. Their expertise regarding both design and development sets the company apart.

Crunch-IS provides ongoing development support that meets project requirements as needed. Despite their offshore location, they are easy to work with and accessible through communication channels

The best vendor we could possibly find. Crunch-IS blends practical development with innovative design principals. Internal and external feedback to app development has been positive. They complete project milestones by the planned schedule and deliver within budget. The team’s responsive and willing to engage in productive dialogue.

Crunch-IS exceeded my expectations. I appreciated the developers’ resourcefulness in the face of constraints and complex requirements. The company able to deliver and complete the project successfully.

The project has gone smoothly so far. Crunch-IS has an exceptional work ethic. Consequentially, they’ve been able to tackle every challenge that comes their way. They manage day-to-day work on their own well but also communicate with us regularly to make sure we’re on the same page.

The app Crunch-IS worked on is clean, streamlined, and functions as intended. Crunch-IS goes above and beyond to ensure that both teams are in tune. The passionate team crafts an enjoyable experience through their positive demeanor and effective project management skills. The team was very friendly, and working with them was a pleasure.

Why Choose Crunch-IS as Your Partner

We Design for Production Conditions
Most pipeline failures happen in the gap between test data and real operational loads. We build and validate against the data volumes, schema variations, and source inconsistencies your system will actually encounter.

AI-Driven Engineering
We apply AI to solve real engineering problems: automated anomaly detection, intelligent schema monitoring, LLM-assisted transformation of unstructured data, and AI-driven pipeline diagnostics.

Data Migrations Are a Core Practice, Not an Edge Case
Migrations fail when teams treat them as a single cutover event. We run them in controlled stages — pre-migration audit, parallel validation, acceptance-tested transfer, reconciliation sign-off.
Data Engineering Services FAQ
What is data engineering?
Data engineering is the discipline of designing, building, and maintaining the infrastructure that makes raw data usable. This includes building pipelines that collect data from multiple sources, transform it into consistent formats, store it in structures that support analysis, and keep the whole system running reliably at scale. Data scientists, analysts, and product teams all depend on this infrastructure — when it is solid, everyone works faster; when it is not, the whole organization feels it.
What is the difference between data engineering and data science?
Data engineering builds the systems that collect, clean, and deliver data in a usable state. Data science works with that data to run analyses, build models, and generate predictions. They depend on each other: data science only produces reliable results when the underlying infrastructure is sound. In most organizations, the fastest way to improve analytical output is to improve data engineering quality first.
How do you handle data migrations without disrupting operations?
We run migrations in stages. The first phase is a full audit of the source environment — schema mapping, data quality assessment, and gap identification. We execute transfers in controlled batches, with validation checkpoints at each stage, and run parallel environments when needed to confirm the output before decommissioning the source. Post-migration, we run reconciliation checks against agreed acceptance criteria. Nothing is signed off on a single cutover.
What data sources can you integrate?
Most relational databases (PostgreSQL, MySQL, SQL Server, Oracle), cloud storage (S3, Azure Blob, GCS), SaaS APIs (Salesforce, HubSpot, Stripe, and similar), message queues (Kafka, Kinesis, RabbitMQ), flat files (CSV, JSON, Parquet), and legacy systems with custom protocols. The integration approach — direct connectors, custom Python extractors, or managed tools like Fivetran — is selected based on reliability requirements and maintenance overhead.
How do you handle security and compliance in data pipelines?
Access controls, encryption, and audit logging are built into the platform architecture during the design phase. Role-based permissions limit who can read or modify each dataset. Data in transit is encrypted; data at rest uses platform-native encryption mechanisms on AWS, Azure, or GCP. For regulated environments, we document data handling practices against GDPR, HIPAA, or SOC 2 requirements and can provide architecture documentation for compliance review.
How is Python used in data engineering?
Python is the standard language for data engineering due to its robust ecosystem. Apache Airflow — the most widely used pipeline orchestration framework — is Python-native. PySpark handles distributed data processing at scale. dbt integrates with Python for testing and transformation workflows. Pandas and SQLAlchemy cover extraction, transformation, and database connectivity.
Crunch-IS Success Stories
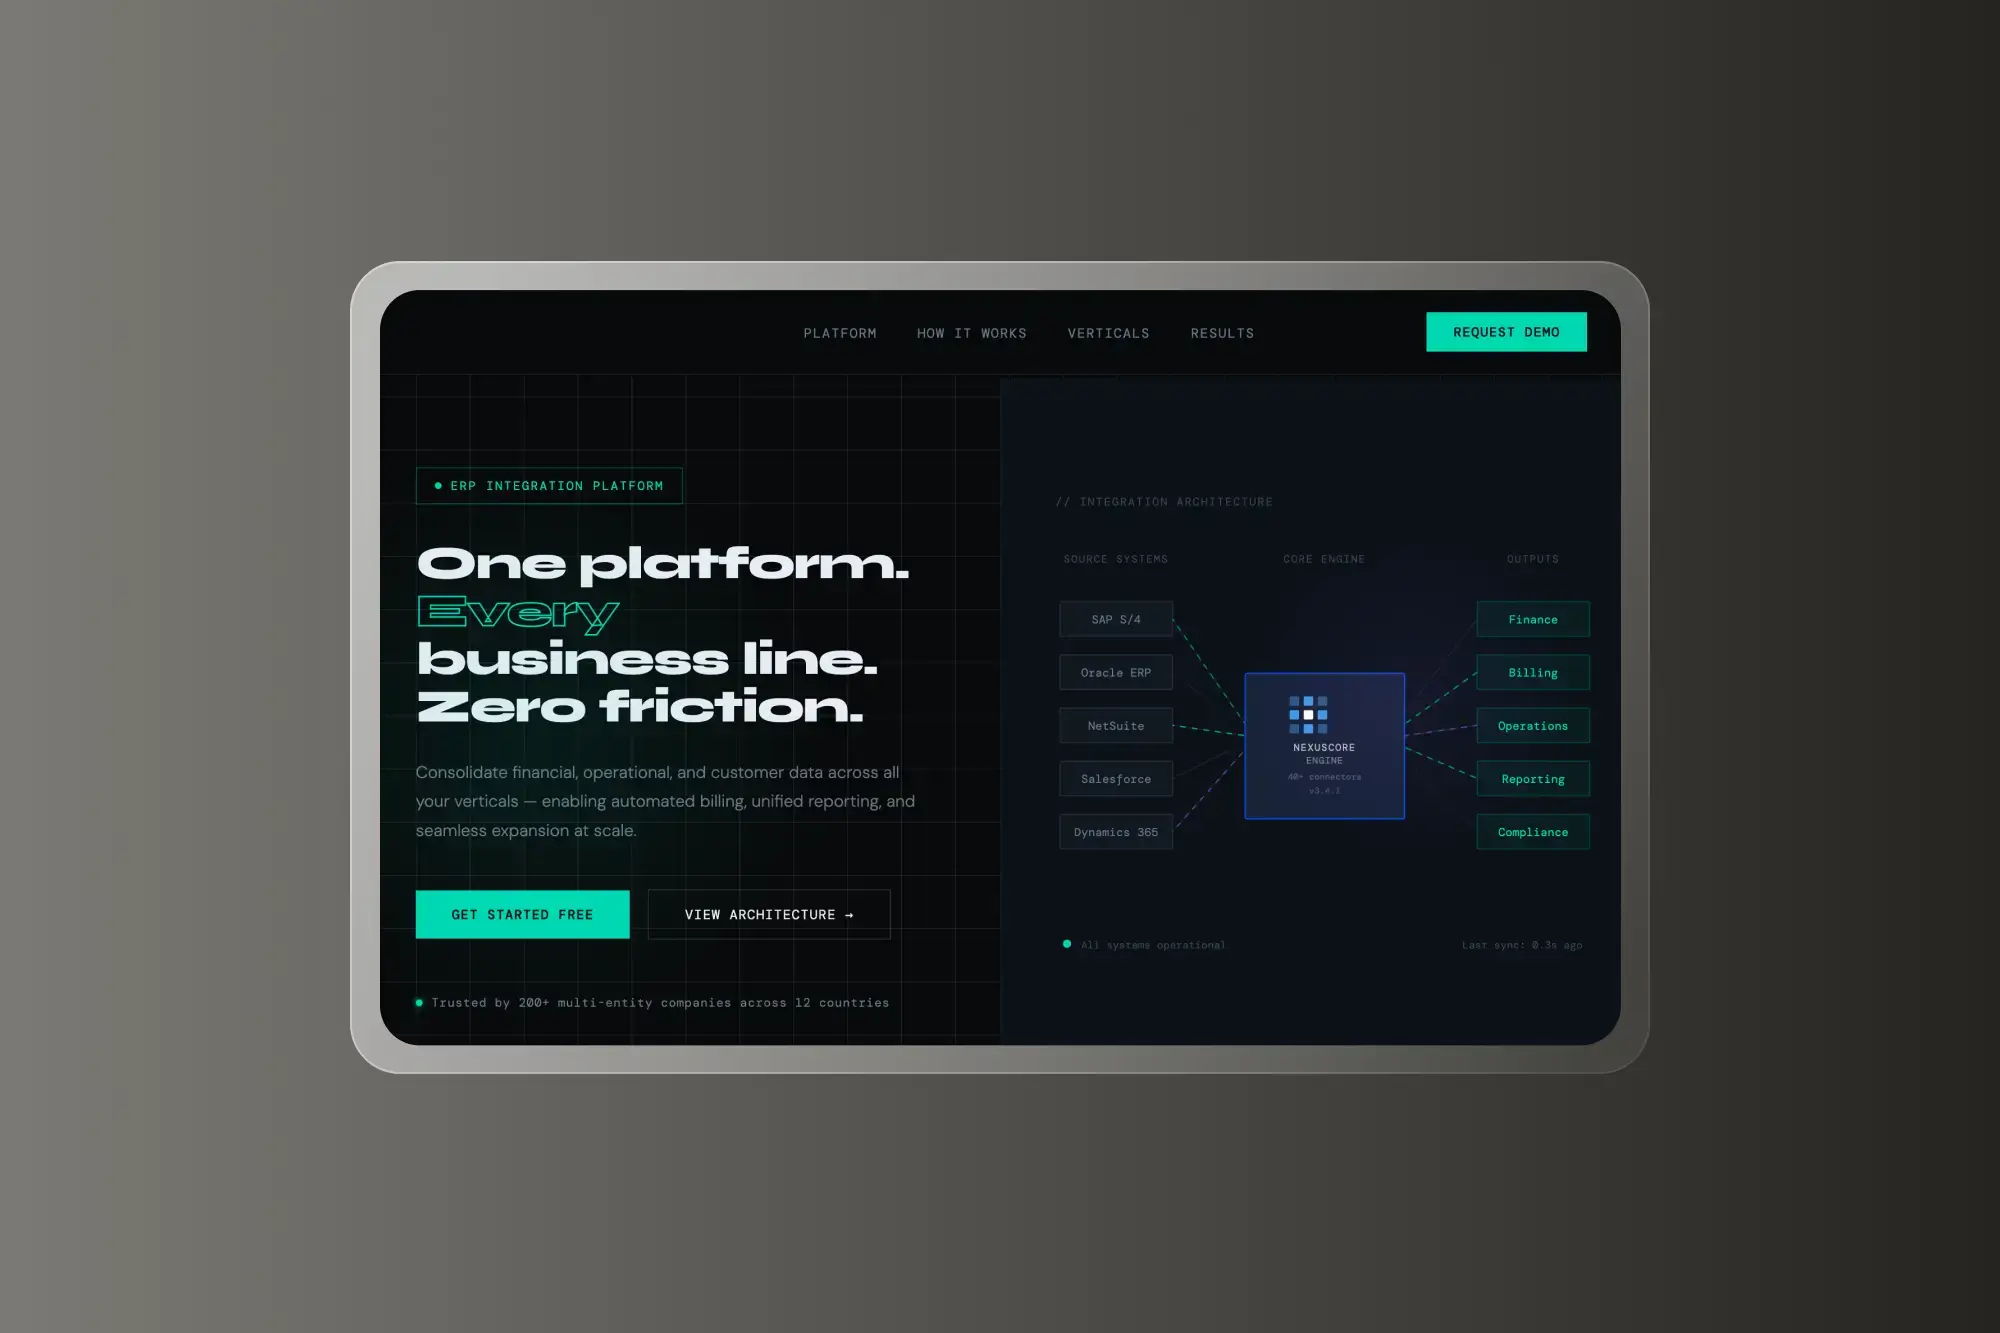
A unified ERP integration platform that consolidates financial, operational, and customer data...

We built an AI-powered analytics platform designed to transform unstructured financial and...
Have a Question? Let’s Get in Touch!
Tell us what you’re building or where you’re stuck. We work with engineering and product teams on custom software, AI & ML, cloud infrastructure, DevOps, and UI/UX — from early scoping to long-term delivery. One conversation is usually enough to know whether we’re the right fit.
Email: [email protected]


