End-to-End Platform for Auditable Scope 2 Carbon Forecasting

92%
invoice field extraction F1-score
≤5.6% MAPE
energy forecast accuracy
End-to-End Platform for Auditable Scope 2 Carbon Forecasting | Crunch-IS Case Study
We built a production MLOps platform that unifies smart-meter and invoice data into a versioned feature store, trains and governs time-series forecasting models on a weekly automated cycle, and delivers auditable Scope 2 CO₂-e forecasts that satisfy CSRD and ISO 14064-1 reporting requirements.
Industry:

Environmental Services & ESG Analytics

Location:

Germany

Team Size:

6

Duration:

6.5 months

Technologies
Statsmodels (SARIMAX)
Temporal Fusion Transformer (TFT)
Optuna (HPO)
Docling (OCR)
Vertex AI Text Embeddings
Qdrant Vector Search
BigQuery
Cloud Functions
Cloud Run
Cloud Scheduler
MLflow (Tracking & Registry)
DVC
Vertex AI Pipelines
GitHub Actions
Cloud Build
Cloud Deploy (Blue-Green)
Dataplex
Cloud Monitoring
Secret Manager
Terraform (IaC)
01

About the Client

The client provides automated ESG disclosure solutions for mid-size manufacturing companies across the EU. Their product delivers Scope 2 carbon reporting data to customers who submit it directly to financial auditors and environmental regulators.

Accuracy and reproducibility aren’t differentiators for this client — they’re the product. Every forecast the platform produces must be traceable, versioned, and defensible under audit.
End-to-End Platform for Auditable Scope 2 Carbon Forecasting | Crunch-IS Case Study
02

Challenge

Scaling the platform required solving four compounding problems:

1. Unstructured Invoice Data at Scale.

Around 40% of the client’s data sources were PDF invoices. Template-based OCR had already failed. The platform needed to extract key fields — kilowatt-hours, dates, tariff codes — reliably across document formats that varied by supplier and country.

2. Multi-Horizon Forecasting.

The business required energy usage forecasts across three time horizons simultaneously: daily, monthly, and a rolling 12-month outlook. A single model serving all three wasn’t viable — the forecasting layer had to be structured to handle each horizon accurately.

3. Emission Factor Currency.

Scope 2 compliance requires multiplying consumption forecasts by the correct country-specific grid emission factor for the period being reported. These factors change periodically. The platform needed to apply the right factor to the right historical window — consistently and automatically.

4. Audit-Grade Release Controls.

Regulators required proof that new model versions entered production through staged, controlled releases — and that any production version could be rolled back near-instantaneously if performance degraded.

03

Solution We Delivered

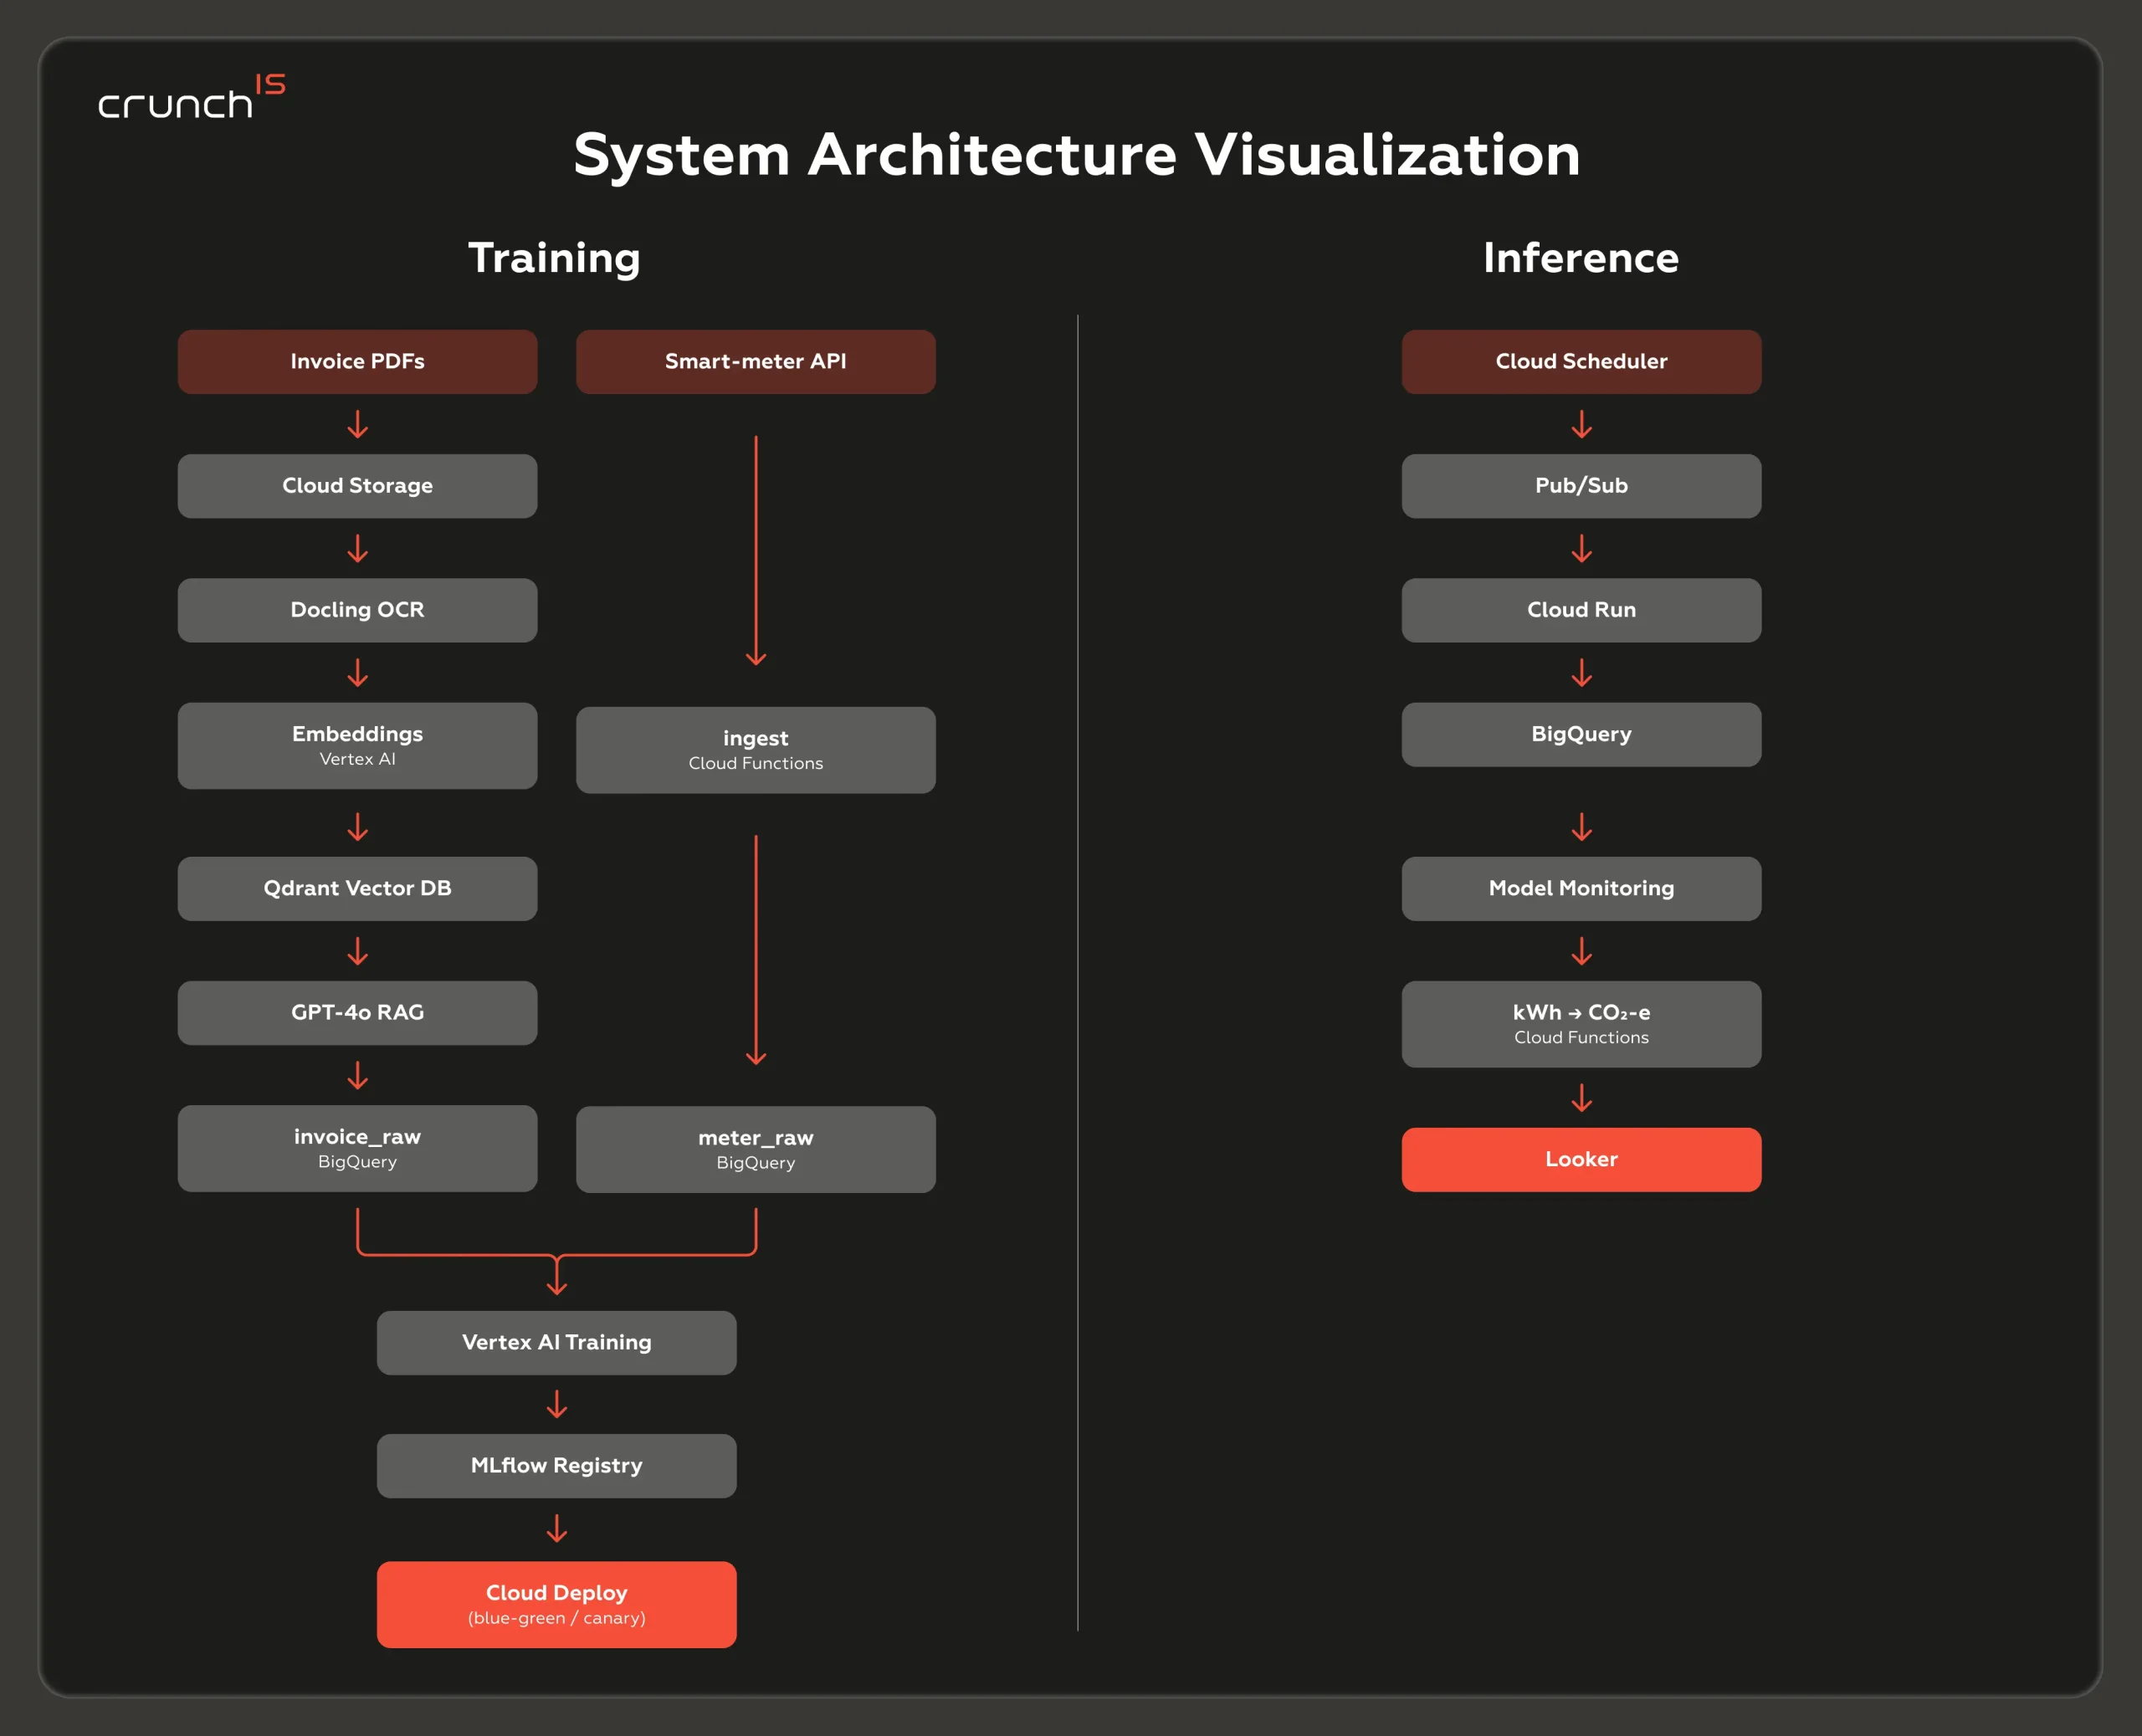
We designed and implemented a modular, cloud-native MLOps architecture covering data ingestion, feature management, model training, inference, and observability — built from the start for regulatory auditability.

Dual-Path Data Ingestion

Structured and unstructured data enter the platform through separate pipelines that converge at a single feature store. Smart-meter readings are ingested via a serverless Cloud Function that pulls hourly API data and directly loads it into BigQuery.

For invoices, a document processing pipeline triggers on upload: Docling extracts raw text via OCR, Vertex AI converts it into vector embeddings, and a RAG flow using Qdrant and GPT-4o pulls the relevant fields — kWh consumed, billing dates, and tariff — with an F1-score of 92%.

Versioned Feature Store

Both data streams are cleaned, transformed, and joined in BigQuery using dbt models, producing a single source of truth for model training. Every dataset snapshot is version-controlled with DVC. Grid emission factors from IEA and EU sources are maintained as a Slowly Changing Dimension table to preserve historical accuracy for past reporting periods.

Automated Model Training and Governance

A weekly Vertex AI Pipeline job retrains a SARIMAX model, with a Temporal Fusion Transformer running as a challenger. Optuna handles hyperparameter optimization. MLflow logs all parameters, metrics, and artifacts for every run. Models achieving an MAPE below 6% are versioned and promoted to the @champion alias in the MLflow Model Registry — the only models eligible for production inference.

Scheduled Inference and Emissions Calculation

A daily Cloud Run service pulls the registered @champion model, loads the latest features from BigQuery, generates forecasts across all required time horizons, multiplies them by current emission factors, and writes the final CO₂-e values to a dedicated predictions table. The output feeds directly into auditable Scope 2 dashboards in Looker.

CI/CD, Data Quality, and Observability

Commits to the main branch trigger GitHub Actions, which build and test container images in Cloud Build before publishing to Artifact Registry. Cloud Deploy executes blue-green rollouts for every release.

The training pipeline runs a Great Expectations validation suite before model training begins — if schema drift or significant statistical shifts are detected, the run halts automatically.

A Vertex AI Model Monitoring job runs daily, detecting prediction and feature drift and paging the on-call team via PagerDuty when performance degrades beyond defined SLOs.

All sensitive credentials are stored in Secret Manager and injected at runtime. Structured logs feed Cloud Monitoring dashboards covering latency, error rates, and pipeline health.

Crunch-IS image case study
04

Client’s Results

Delivered in 6.5 months, the platform produced measurable outcomes across forecasting accuracy, data quality, and release governance:

Auditable Forecasts at Production Quality

The platform delivers weekly-retrained Scope 2 CO₂-e forecasts with a MAPE of ≤5.6% — within the performance threshold required for the client’s regulatory reporting commitments. Every forecast is traceable to the model version, dataset snapshot, and emission factor that produced it.

Invoice Processing That Works

The document intelligence pipeline achieves a 92% F1-score for invoice field extraction, replacing the template-based OCR approach that had already been abandoned. Unstructured invoice data now enters the feature store on the same cadence as structured API data, without manual correction.

Controlled Releases, One-Click Rollback

Every model version is deployed to production via an automated blue-green deployment. If performance degrades, the previous champion can be restored in a single step. Regulators receive proof of staged, controlled release processes as part of the audit record.

Fully Automated Operations

The platform runs without manual intervention across ingestion, training, inference, and monitoring. Data quality guardrails prevent bad data from reaching a model. Drift detection surfaces degradation before it affects the reporting output.

Have a Question? Let’s Get in Touch!

Tell us what you’re building or where you’re stuck. We work with engineering and product teams on custom software, AI & ML, cloud infrastructure, DevOps, and UI/UX — from early scoping to long-term delivery. One conversation is usually enough to know whether we’re the right fit.

Email: [email protected]

    I have read and accepted the Terms of Use and Privacy Policy *

    We and our partners use technology such as cookies on our site to personalize content and ads, provide social media features, and analyze our traffic. Click “Accept” to consent to the use of this technology across the web.

    Decline