A ten-person team, and half of it is waiting. The backend lead is blocked on requirements. QA is blocked on the backend. The project manager spends every standup collecting status instead of clearing obstacles. The estimate said eight months, and each week of coordination makes that number harder to defend.
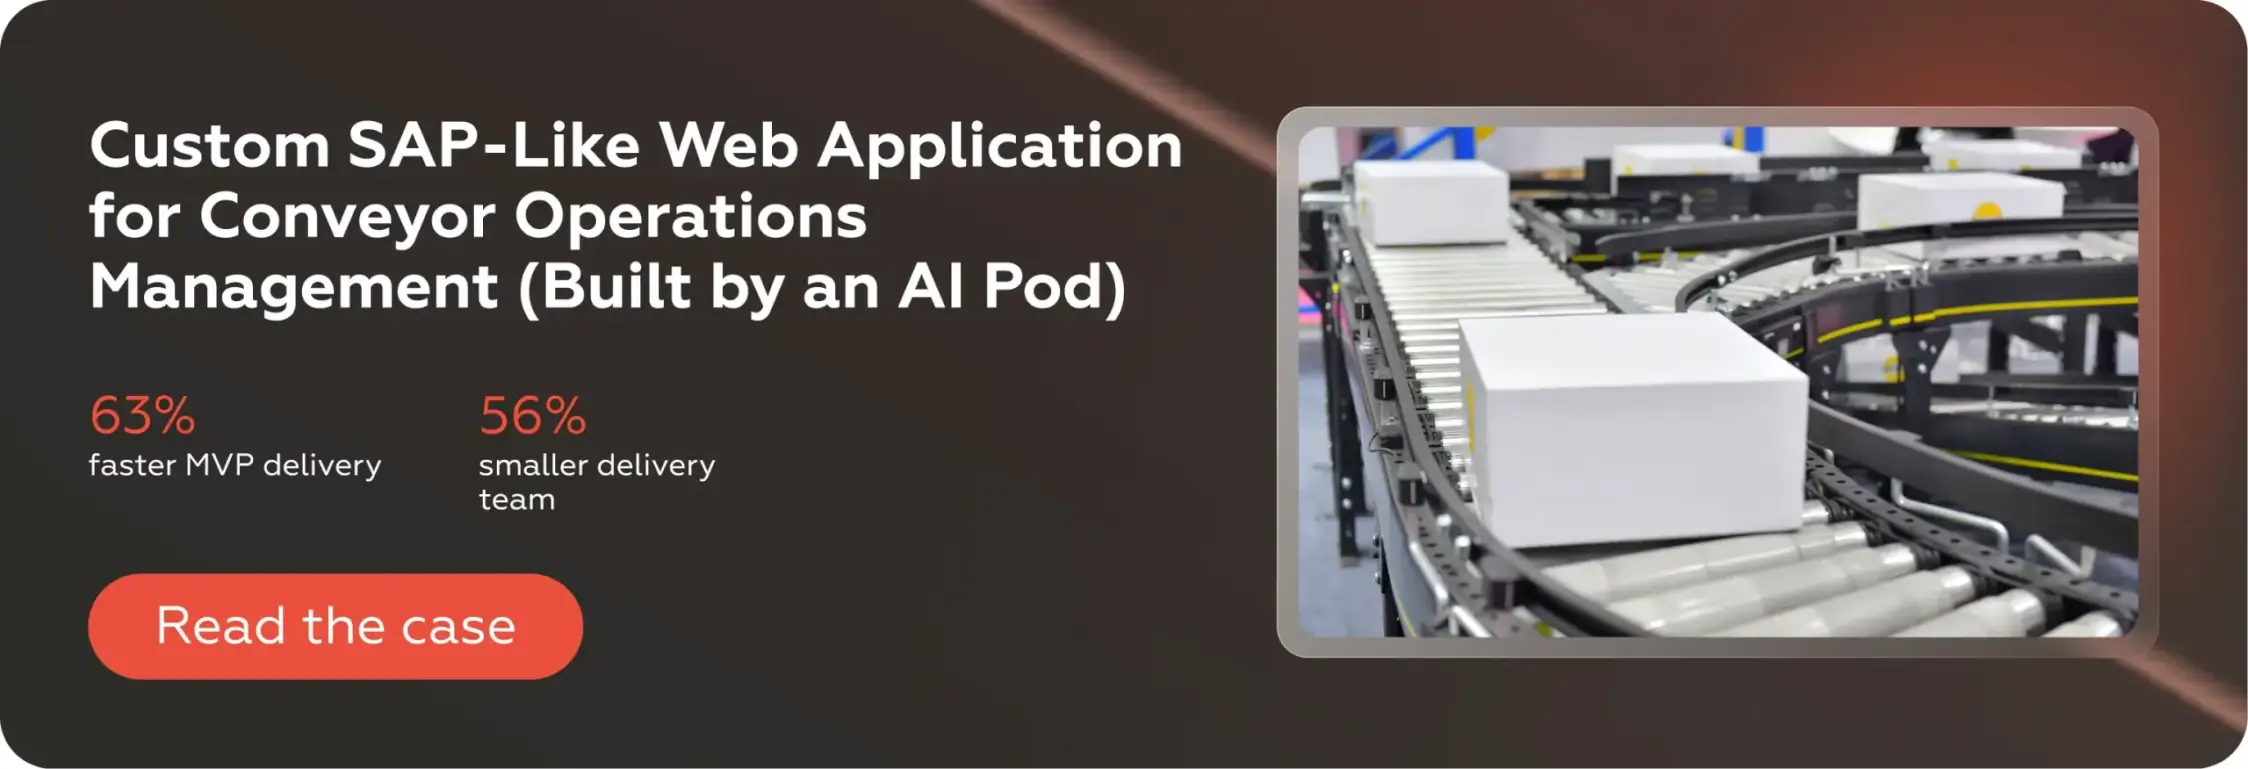
When a UK manufacturer brought us a build of exactly that scope — a custom, SAP-integrated system to replace spreadsheet-run conveyor operations — a traditional team would have needed those eight months. An AI Pod of four senior specialists delivered the MVP in three, with the plant running on its existing SAP and Google Sheets data throughout.
That result comes from a different way of structuring delivery, and this article explains how it works: what an AI Pod is, where the speed comes from, what it costs relative to a traditional team, and where the model fits.
What is the AI Pod model? An AI Pod is a compact delivery team of 3–5 senior specialists who work with AI agents embedded throughout the software development lifecycle. The AI in software development handles the volume — code generation, test coverage, documentation, requirements drafts — while the engineers own every decision: architecture, review, and accountability for each line that ships. The team stays small, so the coordination overhead that grows with headcount never appears in the first place.
For a deeper look at how AI embeds across individual SDLC phases, see our guide to AI-enabled engineering across the software development lifecycle.
- An AI Pod comprises 3–5 senior specialists who work with AI agents throughout the full development lifecycle. The AI produces volume; the engineers own the decisions.
- The speed comes from removing coordination overhead rather than managing it. A four-person Pod delivered MVP in 3 months against an 8-month traditional estimate.
- Quality holds because review is structural. Every AI-generated output passes senior review before it ships, and the same discipline has carried a production migration at 40% above baseline speed.
- The model fits scoped builds, MVPs under deadline, and modernization workstreams. Large multi-stream enterprise programs still call for a different structure — and we say so.
How an AI Pod Works
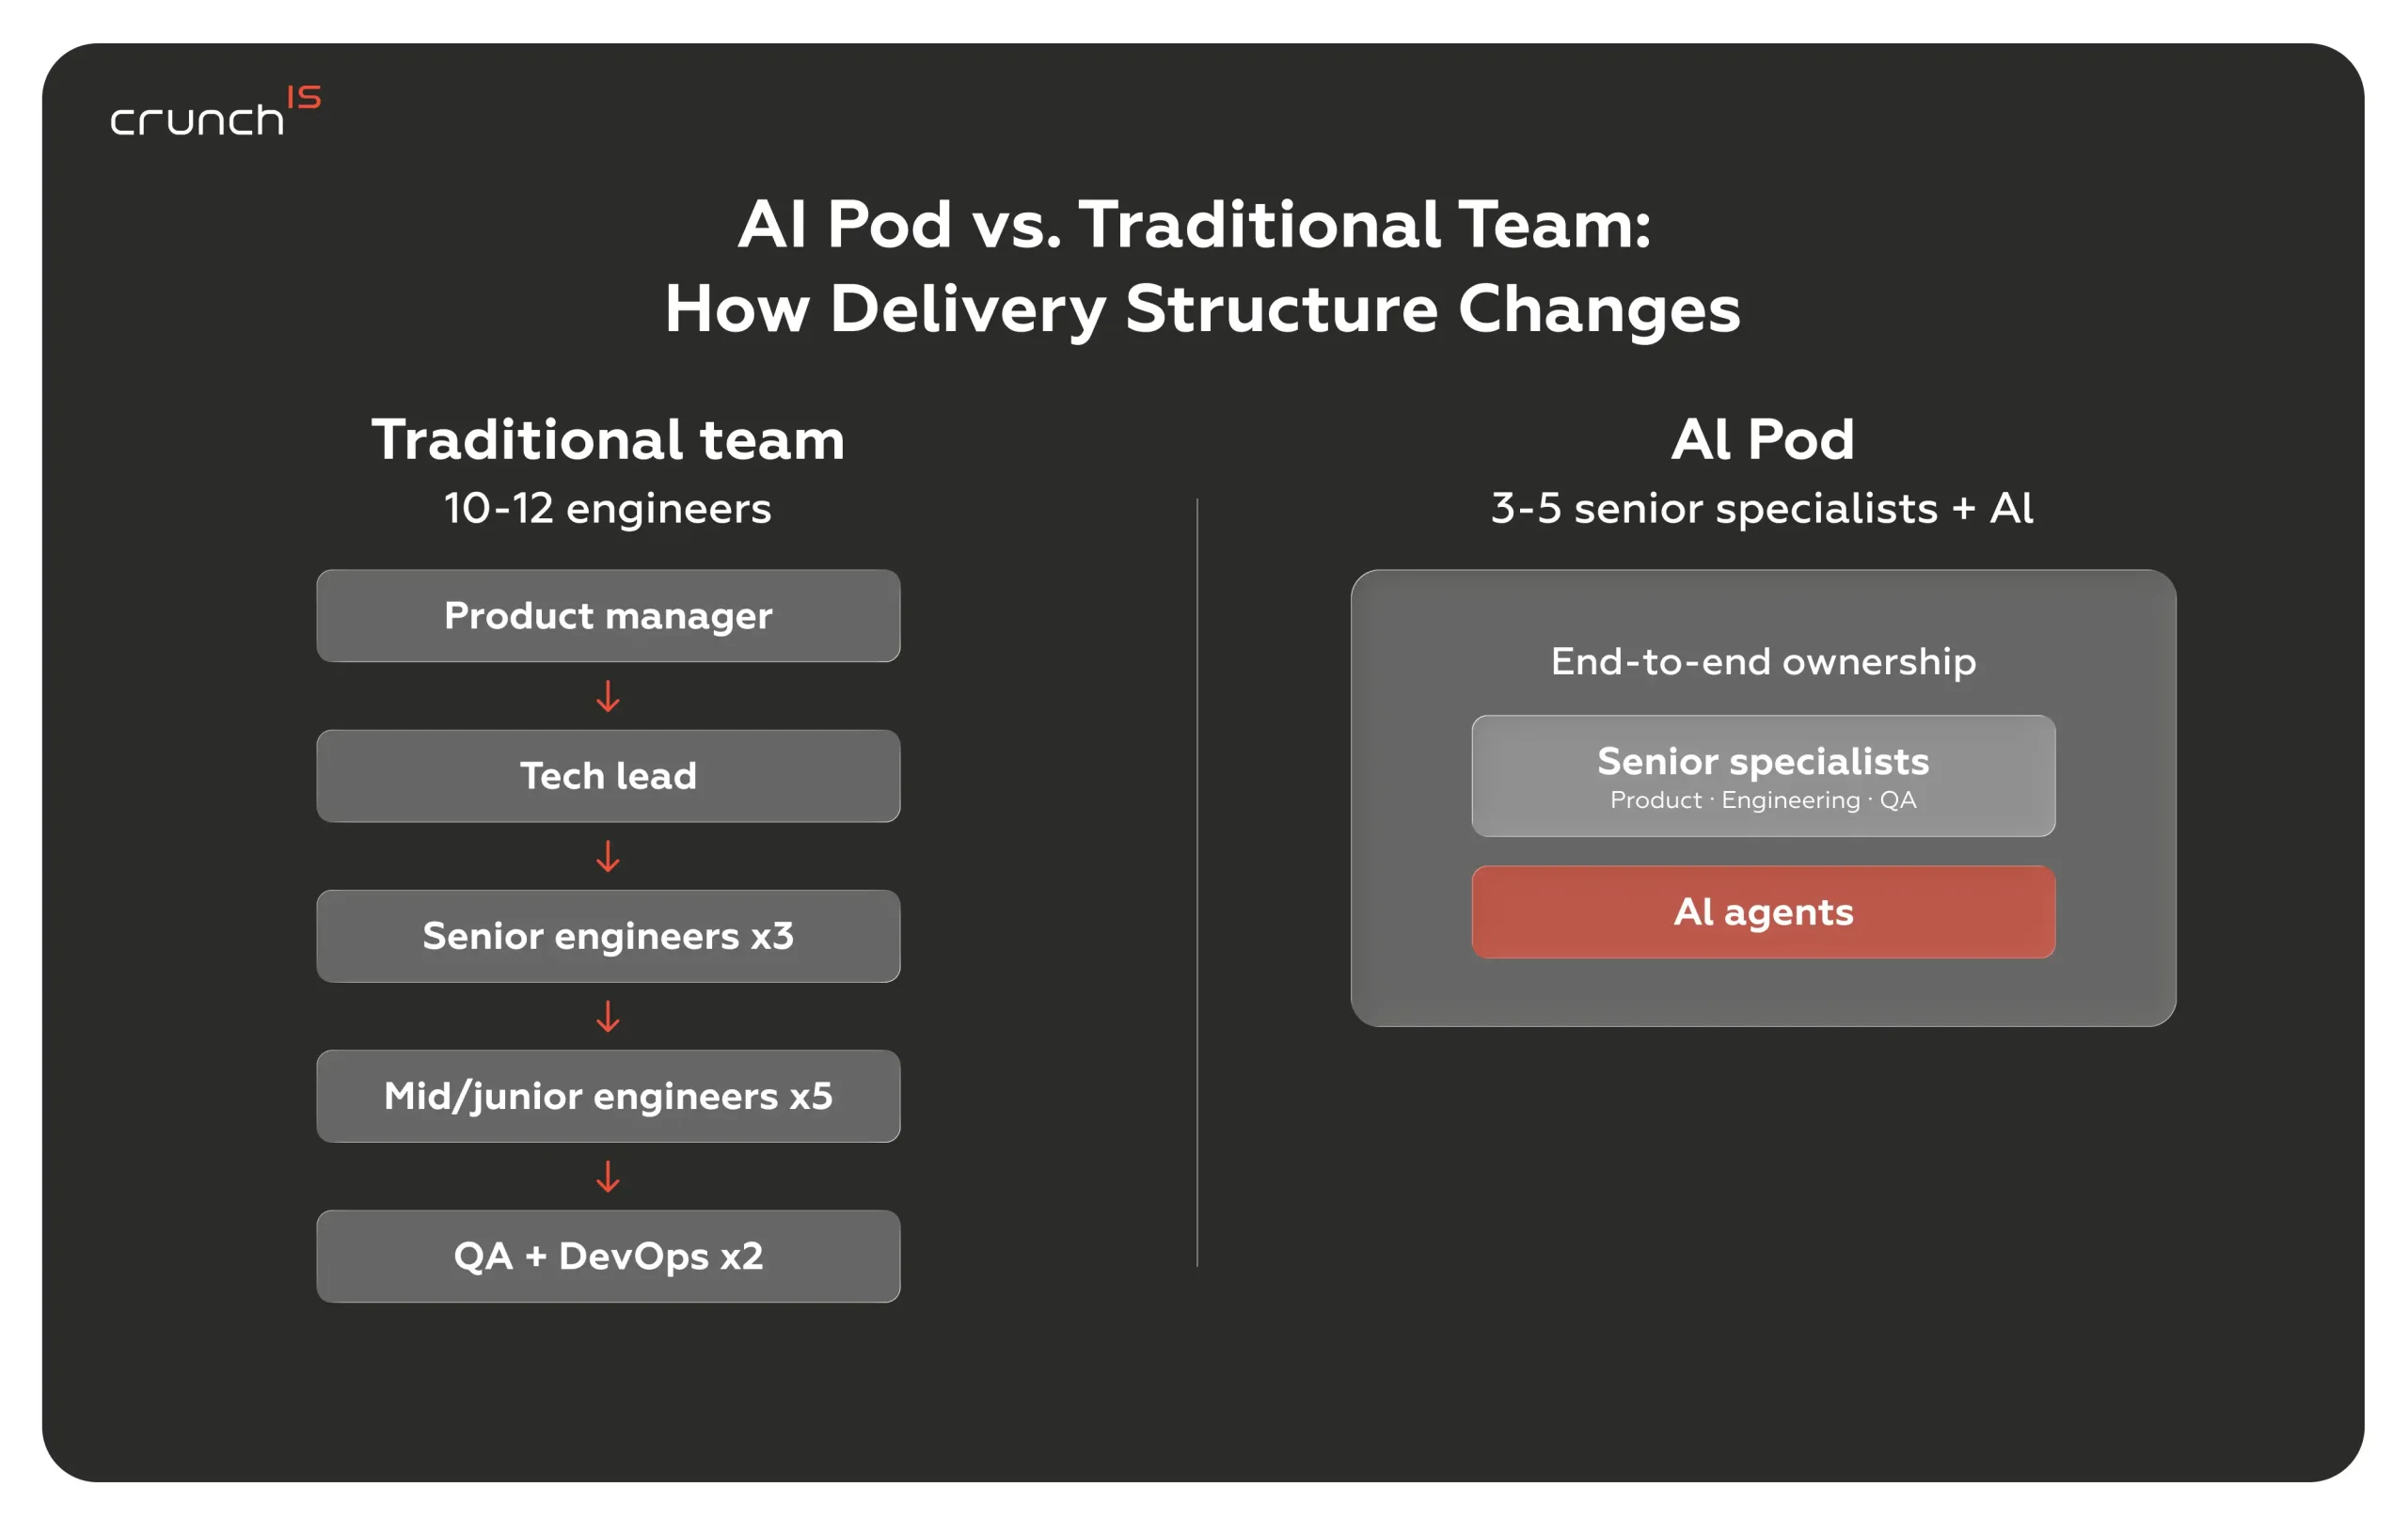
A Pod is deliberately small: 3–5 senior specialists, typically a lead architect and engineers whose mix depends on the build — backend, frontend, QA, data. There is no junior layer to supervise and no separate documentation or reporting role, because that work has moved to the AI.
The AI agents operate across every stage of delivery. During scoping, they draft requirements and edge cases from source material for the lead to correct and approve. During the build, they generate implementation code, produce test coverage alongside it, and keep documentation current with the codebase instead of behind it. During review, they run a first analytical pass so that senior attention goes to design decisions rather than syntax.
The engineers do the part that cannot be delegated. They make the architecture calls, define what “done” means for each piece of work, review everything the AI produces, and carry accountability for every line that reaches production. The ratio is the point: a small number of experienced people directing a large amount of generated output, with nothing merging unreviewed.
Day to day, this changes the shape of the work. A specialist takes a feature from requirement to tested code without handing it across three roles, and the feedback loop that used to span a sprint now closes within a day.
The Hidden Cost of Traditional Engineering Teams
Coordination Overhead Kills Delivery Speed
A ten-person engineering team doesn’t produce ten times the output of one engineer. It produces something closer to three or four times, and the gap is coordination loss. Every handoff between design, development, and QA creates wait time. Every additional stakeholder in a requirements discussion expands the surface area for misalignment. Every review layer adds latency before code ships.
Brooks’s Law describes this dynamic at the extreme: adding people to a late project makes it later. The underlying mechanism, though, is always present at scale. Larger teams don’t just cost more to staff — they cost more to coordinate, and that cost compounds faster than output does.
How Pyramid Staffing Inflates Cost Per Feature
Traditional delivery teams are built like pyramids: a handful of senior engineers at the top, a broader mid-level, and a base of juniors handling volume work under supervision. This model made sense when senior time was the bottleneck and junior output was the affordable alternative.
AI inverts the logic. Junior-heavy pyramid structures produce more code to review, more defects to catch, and more context switching for seniors, who end up managing output rather than directing architecture. BCG’s 2026 research on AI job transformation finds that under AI adoption, senior workers expand their responsibilities and productivity, while entry-level positions shrink in scope. The pyramid model spreads cost across headcount without focusing on quality, and the economics only worsen as AI-assisted software development becomes the baseline.
How the AI Pod Model Rebalances Delivery Economics
A compact AI Pod — typically 3–5 senior specialists with AI embedded across the delivery workflow — produces output that previously required teams twice or three times as large. BCG estimates that AI-powered coder augmentation alone yields productivity gains of 30–50%. McKinsey research, drawing on data from over 600 organizations, found that companies achieving 80–100% AI adoption across engineering report gains exceeding 110%.
The directional shift is visible in how leading organizations are redesigning their own teams. In a 2026 McKinsey webinar on enterprise AI transformation, McKinsey senior partner Rob Levin described the emerging model as “collapsing the two-pizza team of around eight people to two: a product owner who knows what good looks like, and a full-stack engineer who can work with code-writing systems, debug it, and work it into the architecture.”
Senior-Only Pods: Lower Cost Per Outcome
AI Pods run on senior-only composition — not because junior engineers lack value, but because AI now handles the volume of work that justified hiring them: boilerplate, test generation, documentation, and initial code drafts. What remains at the Pod level requires judgment.
Senior-only pods cost more per head but less per outcome. Fewer engineers means fewer salaries, fewer onboarding cycles, less management overhead, and a shorter path from requirement to production. The cost model shifts from paying for capacity to paying for delivery.
Traditional Team vs. AI Pod: What You’re Paying For
Does AI-Powered Development Compromise Quality?
The instinct is to assume smaller teams produce lower-quality output. The evidence doesn’t support it. In a controlled study by GitHub with 243 developers, code produced with AI assistance showed improvements in readability (3.6%), reliability (2.9%), and maintainability scores compared to human-only baselines. Developers were also 5% more likely to approve AI-assisted code in peer review.
Testing, code review, and documentation happen continuously in an AI Pod — built into the workflow, not scheduled for the week before launch. Errors surface when they’re cheap to fix, not after they’ve shipped. By the time the code reaches production, it’s been through more scrutiny than most traditionally staffed teams run in an entire sprint.
This matters commercially. Fewer production defects mean less rework, fewer incident-response cycles, and lower total cost of ownership — gains that accumulate with every release.
Our own proof point runs at production scale. In a live Angular-to-React migration of a production application, the Pod approach moved 1/3 of the application while running 40% faster than the project’s pre-AI baseline — measured on the same codebase, same team, same standards.
Where the Model Fits — and Where It Doesn’t
The Pod model is strongest where scope is defined and the deadline is close: an MVP that has to reach the market, a system replacement that cannot pause operations, a modernization stream inside a larger platform, or a new product line the organization wants to build without expanding the org chart to do it.
It is not the answer to everything. A multi-stream enterprise program with heavy stakeholder management across departments still needs a larger structure, and we scope it that way. Matching the delivery model to the job is part of the engineering.
Conclusion
Smaller teams ship faster when the structure removes coordination instead of managing it. The AI Pod model does exactly that: senior specialists directing AI-generated volume, with review built into every step and results measured in production — a three-month MVP against an eight-month estimate, a live migration running 40% above baseline.